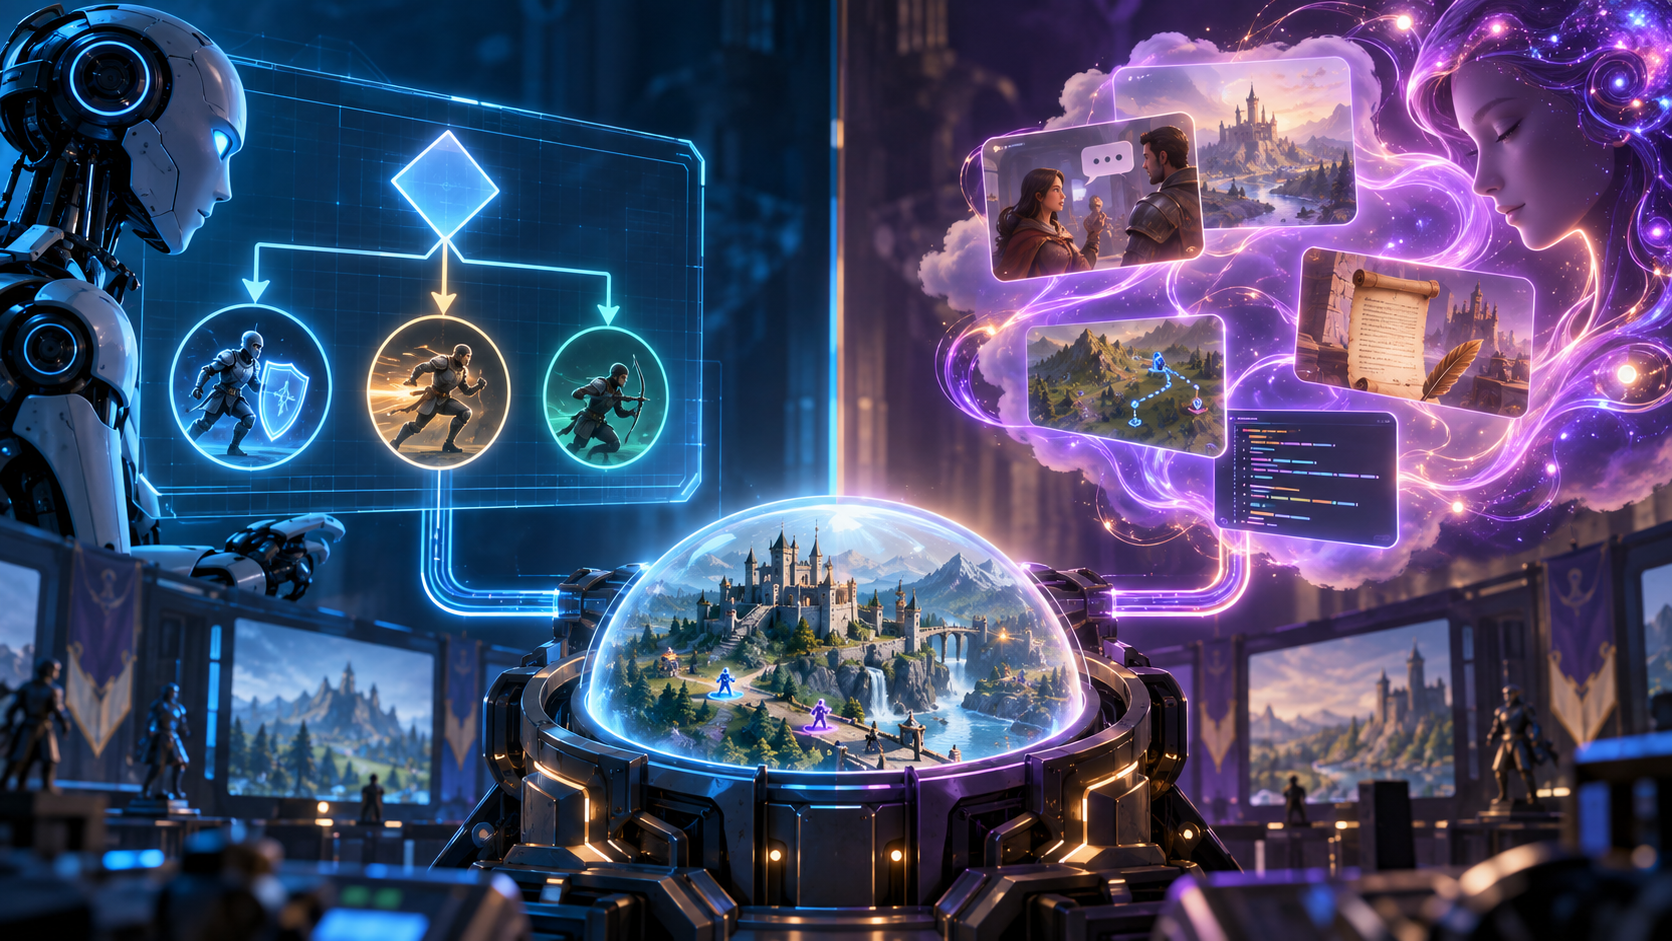
JEV と LLM は、ゲーム内のさまざまな問題を解決します。 LLM は、言語、プラン、コード、ダイアログ、およびオープンエンド命令の汎用ジェネレーターおよびインタープリターです。 JEV は、制限された意思決定機能です。入力された質問に対してゲーム状態の予測を評価し、Choice、Score、またははい/いいえの判断などの制約された結果を返します。最良のアーキテクチャでは、多くの場合、両方が使用されます。短い答えゲームが実行可能な選択肢を認識しており、それらについて型付けされた判断が必要な場合は、JEV を使用します。 LLM は、対話、物語、説明、コード、オープンエンドの生成、または長期の計画に使用します。どちらも権威あるゲームルールを所有すべきではありません。エンジンは結果を検証して実行します。能力 JEV LLM 1_
出力入力済みChoice、Score、または限定的判断テキスト、コード、プラン、ダイアログ、または構造化出力
_最高フィット状態の評価と候補アクションの選択会話、物語、計画、世代アクションスペース
| _クローズおよび検証済みの候補自由回答可能性 | _ゲーム役割意思決定層または戦術層対話、コンテンツ、およびハイレベル計画 | JEV が返す内容パブリックJEVマテリアルは、などの型付きプリミティブを記述します。 _Score_、およびNoul_。 Choice は、定義されたセットから 1 つの項目を選択します。 Score は候補者をランク付けします。 Noul は、限定された「はい」または「いいえ」の質問に答えます。ゲームは、無制限の散文を求めるのではなく、質問と許容される結果を定義します。LLM の得意なことLLM は、NPC ダイアログを作成したり、クエスト履歴を要約したり、ミッション概要を生成したり、設計 Choice を説明したり、自然言語をクエスト草案に変換したり、長期計画を提案したりできます。すべての計画は承認されたコマンドに変換され、ゲームの検証境界を通過する必要があります。すべてのティックにLLMを使用しないのはなぜですか?ティックごとの制御により、一般言語インターフェイスがゲーム ループの最も期限に敏感な部分を担当します。出力が遅すぎたり、冗長になったり、無制限になったりする場合があり、動作の再現が困難になります。低レベルのステアリング、衝突、アニメーション、および安全性チェックは通常、決定的です。脅威が出現したとき、アクションが完了したとき、または目標が変更されたときに、戦術的な決定をトリガーします。ハイブリッド JEV および LLM アーキテクチャLLMは、対話、クエストの解釈、または高レベルの計画を処理します。ゲーム コードは、その結果をコンパクトな状態に変換し、終了 Legal Actions.JEV が選択、Score、または戦術をゲート決定。 |
|---|---|---|
| _ビヘイビアー ツリー、アビリティ システム、またはエグゼキューターがアクションを実行します。テレメトリは、状態、遅延、有効性、および結果。意思決定チェックリスト既知のChoice、Score、またははい/いいえの質問: JEV適合します。対話、散文、コード、または自由形式の計画: LLM が適合する可能性があります。 | _ゲームはできますか実行前に結果を検証しますか?期限、フォールバック、および再生可能な状態はありますか?誇大広告ではなく層ごとに比較最も有用な比較は、各システムがゲームのどのレイヤーを所有しているかを尋ねます。認識と権威ある状態はエンジンに属します。戦術的な選択では、制限された意思決定モデルを使用できます。対話と物語には LLM を使用できます。ナビゲーション、アニメーション、物理学、レプリケーションは決定論的である必要があります。この階層化ビューにより、1 つのモデルが NPC 全体を担当するという誤った Choice が回避されます。_3 つのハイブリッド パターンLLM から JEV:_ LLM はプレイヤーのリクエストまたはクエストの目標を解釈し、ゲーム コードがそれを限定された戦術的な質問に変換します。 JEV.JEV までLLM:_ JEV は説明に値する状況または目的を選択し、LLM は対話またはミッションを記述しますupdate.パラレルスペシャリスト: | JEV は、時間に敏感な Choice を作成します。 LLM は、後の瞬間のためにノンブロッキングのダイアログ、メモリ、またはコンテンツを準備します。_3 つのパターンすべてで、ゲームがハンドオフ コントラクトを所有します。自然言語プランは実行可能なコマンドではなく、入力された Choice は検証をバイパスする権限を持ちません。設計対象の障害モードオープンエンド出力:_ 前にクローズド コマンド セットに変換します。 _古い状態:_ バージョンを添付し、それを説明しなくなった結果を拒否します。 world.応答が遅い: |
| 現在のインテントを保持するか、ローカルに切り替えますポリシー. | _プロンプト ドリフト: | 質問スキーマのバージョン管理を維持し、再生可能。役割の混乱:_ コンポーネントが選択するか、説明するか、または選択マトリックス候補がわかっている場合は、JEV を選択してください。決定は入力する必要があり、ゲームは妥当性を評価できます。言語または無制限の生成が呼び出しの結果である場合は、LLM を選択します。コードで簡単に表現できる決定論的なルールの場合は、どちらも選択しません。最良の AI アーキテクチャでは、他のサブシステムと同様に出力をテストできるようになるまで、モデルの責任が軽減されることがよくあります。実装については、JEV API の使用方法 に進みます。 NPC アーキテクチャについては、JEV を参照してください。より広範なコンテキストについては、JEV ゲーム AI_. を参照してください。 |
| Action space | Closed and validated candidates | Open-ended possibilities |
| Game role | Decision or tactical layer | Dialogue, content, and high-level planning |
What JEV returns
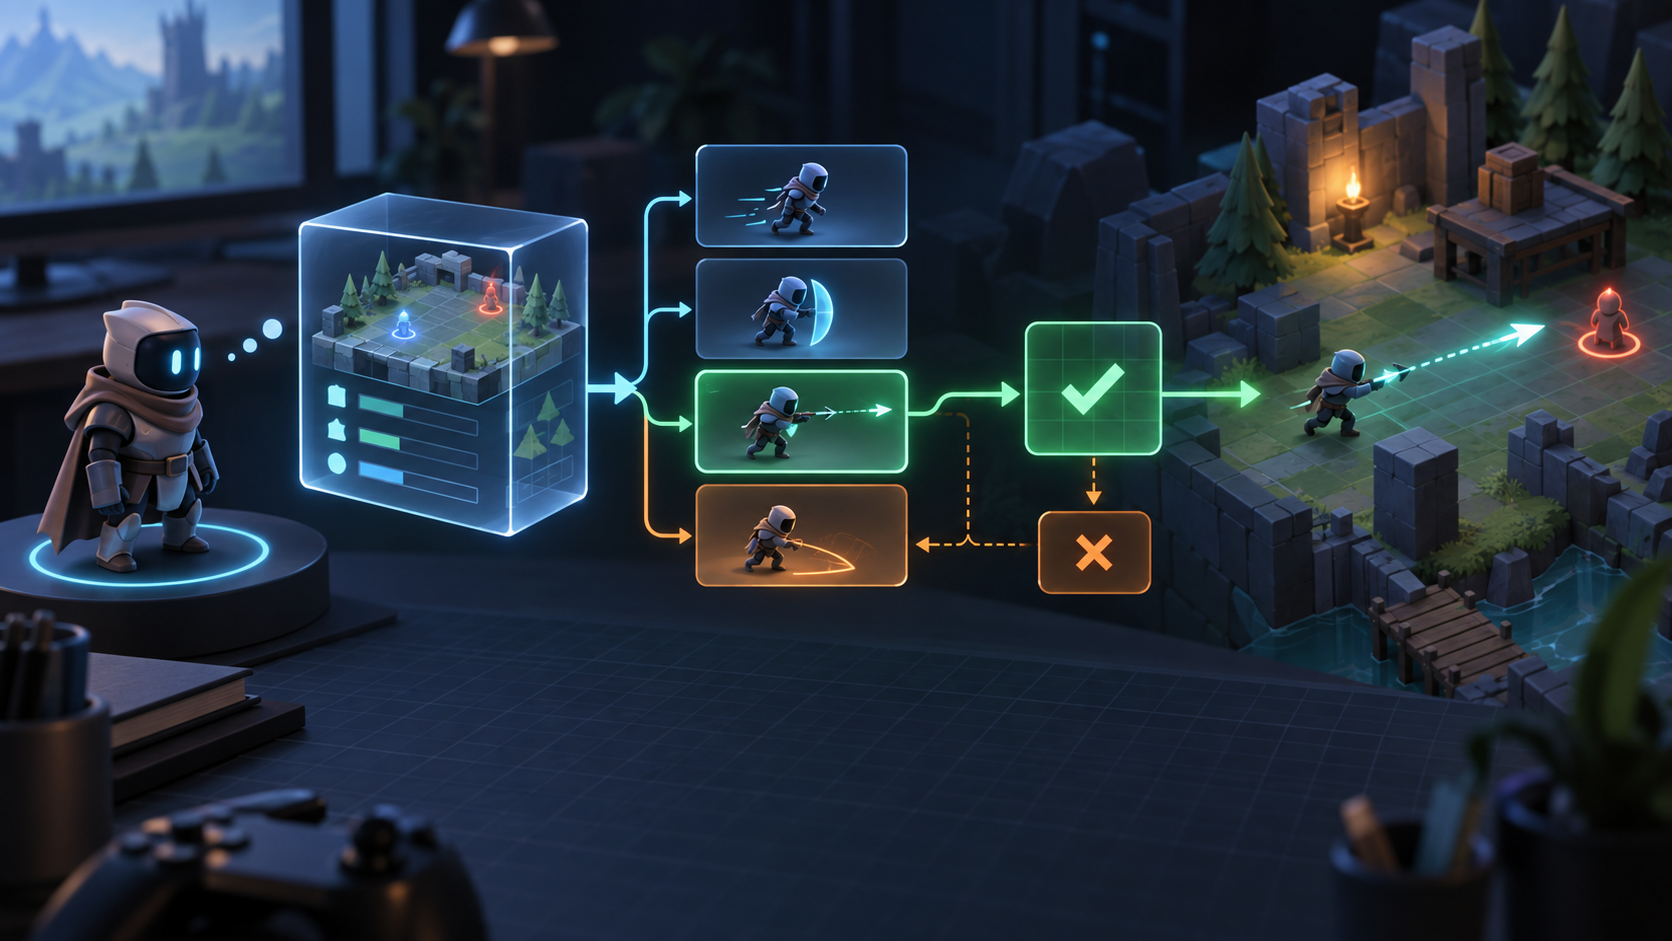
Public JEV materials describe typed primitives such as Choice, Score, and Noul. A Choice selects one item from a defined set. A Score ranks candidates. A Noul answers a bounded yes-or-no question. The game defines the question and allowable result instead of asking for unrestricted prose.
What LLMs are good at
LLMs can write NPC dialogue, summarize quest history, generate mission briefs, explain a design choice, transform natural language into a draft quest, or propose a long-horizon plan. Any plan must still be converted into approved commands and pass the game's validation boundary.
Why not use an LLM for every tick?
Per-tick control makes a general language interface responsible for the most deadline-sensitive part of the game loop. Output may be too slow, verbose, or open-ended, and behavior becomes harder to reproduce. Low-level steering, collision, animation, and safety checks are normally deterministic. Trigger a tactical decision when a threat appears, an action completes, or an objective changes.
A hybrid JEV and LLM architecture
- The LLM handles dialogue, quest interpretation, or a high-level plan.
- Game code translates that result into compact state and closed legal actions.
- JEV chooses, scores, or gates the tactical decision.
- A behavior tree, ability system, or executor performs the action.
- Telemetry records state, latency, validity, and outcome.
Decision checklist
- Known choice, score, or yes-or-no question: JEV may fit.
- Dialogue, prose, code, or open-ended plan: an LLM may fit.
- Can the game validate the result before execution?
- Is there a deadline, フォールバック, and replayable state?
Compare by layer, not by hype
The most useful comparison asks which layer of the game each system owns. Perception and authoritative state belong to the engine. Tactical selection can use a bounded decision model. Dialogue and narrative can use an LLM. Navigation, animation, physics, and replication should remain deterministic. This layered view avoids the false choice of putting one model in charge of the whole NPC.
Three hybrid patterns
- LLM to JEV: the LLM interprets a player request or quest goal, then game code converts it into a bounded tactical question for JEV.
- JEV to LLM: JEV selects a situation or objective that deserves explanation, while the LLM writes dialogue or a mission update.
- Parallel specialists: JEV makes a time-sensitive choice while an LLM prepares non-blocking dialogue, memory, or content for a later moment.
In all three patterns, the game owns the handoff contract. A natural-language plan is not an executable command, and a typed choice is not permission to bypass validation.
Failure modes to design for
- Open-ended output: convert it into a closed command set before execution.
- Stale state: attach a version and reject results that no longer describe the world.
- Slow response: preserve the current intent or switch to a local policy.
- Prompt drift: keep question schemas versioned and replayable.
- Role confusion: document whether a component chooses, explains, or executes.
Selection matrix
Choose JEV when the candidates are known, the decision must be typed, and the game can evaluate validity. Choose an LLM when language or open-ended generation is the product of the call. Choose neither for a deterministic rule that is already easy to express in code. The best AI architecture often reduces the model's responsibility until its output can be tested like any other subsystem.
For implementation, continue to JEV API usage. For NPC architecture, read JEV NPC. For broader context, see JEV Game AI.