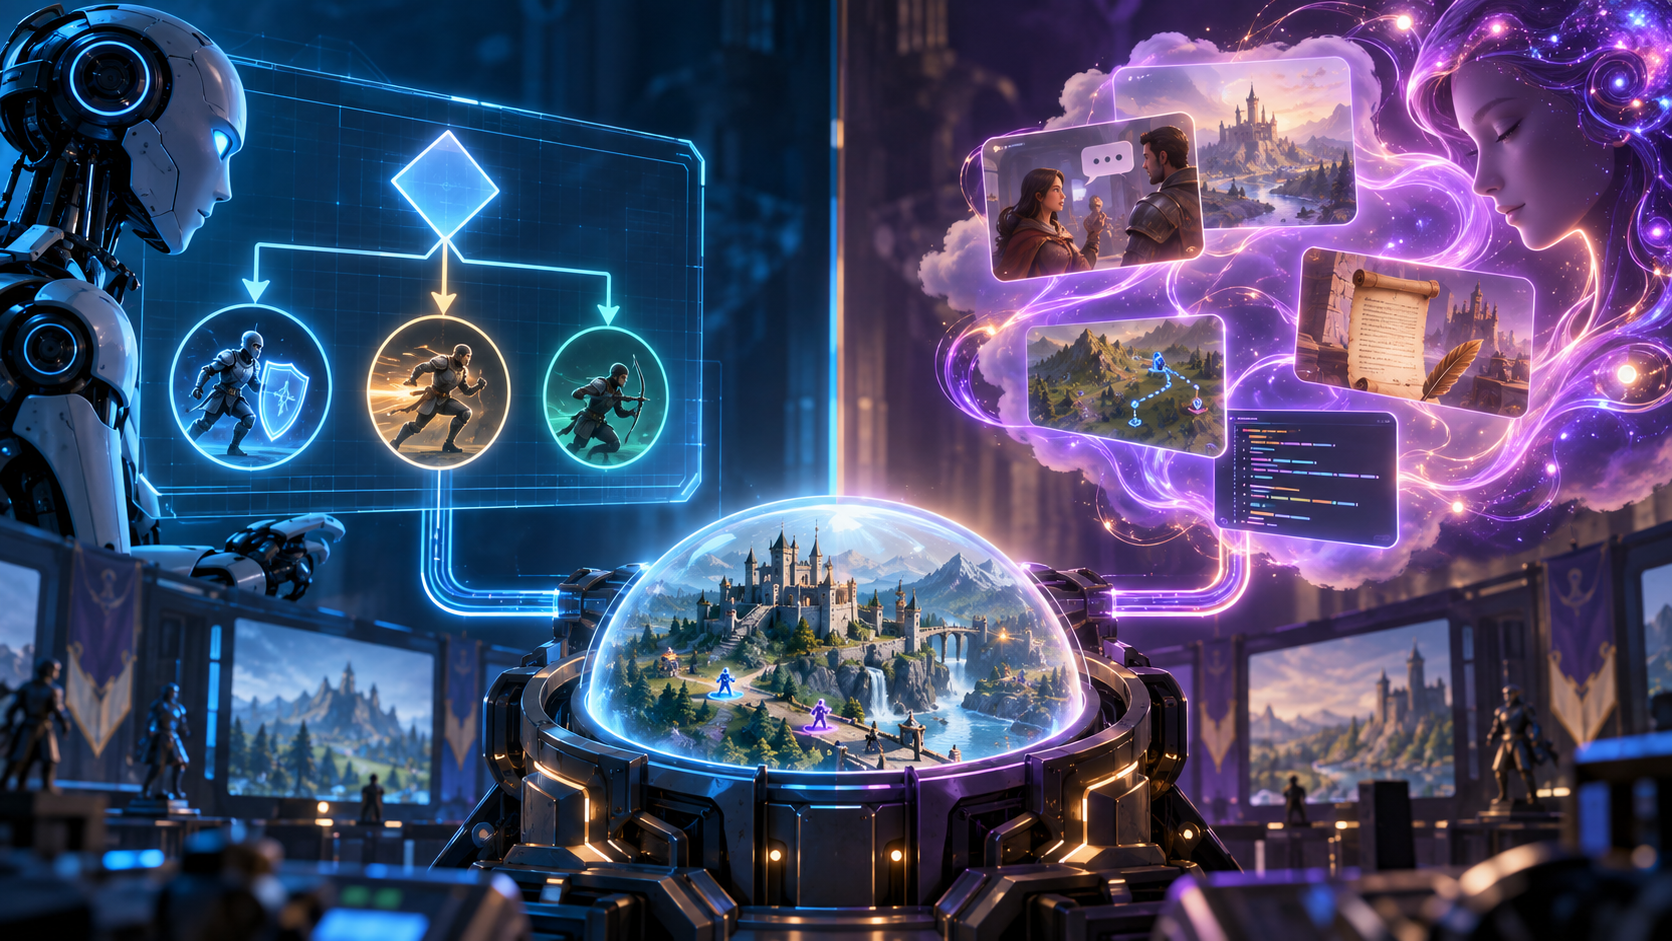
JEV and LLMs solve different problems in a game. An LLM is a general-purpose generator and interpreter for language, plans, code, dialogue, and open-ended instructions. JEV is a bounded decision capability: it evaluates a game-state projection against typed questions and returns a constrained result such as a choice, score, or yes-or-no judgment. The best architecture often uses both.
The short answer
Use JEV when the game knows the legal options and needs a typed judgment about them. Use an LLM for dialogue, narrative, explanation, code, open-ended generation, or longer planning. Neither should own authoritative game rules; the engine validates and executes results.
| Capability | JEV | LLM |
|---|---|---|
| Output | Typed choice, score, or bounded judgment | Text, code, plans, dialogue, or structured output |
| Best fit | State evaluation and candidate-action selection | Conversation, narrative, planning, and generation |
| Action space | Closed and validated candidates | Open-ended possibilities |
| Game role | Decision or tactical layer | Dialogue, content, and high-level planning |
What JEV returns
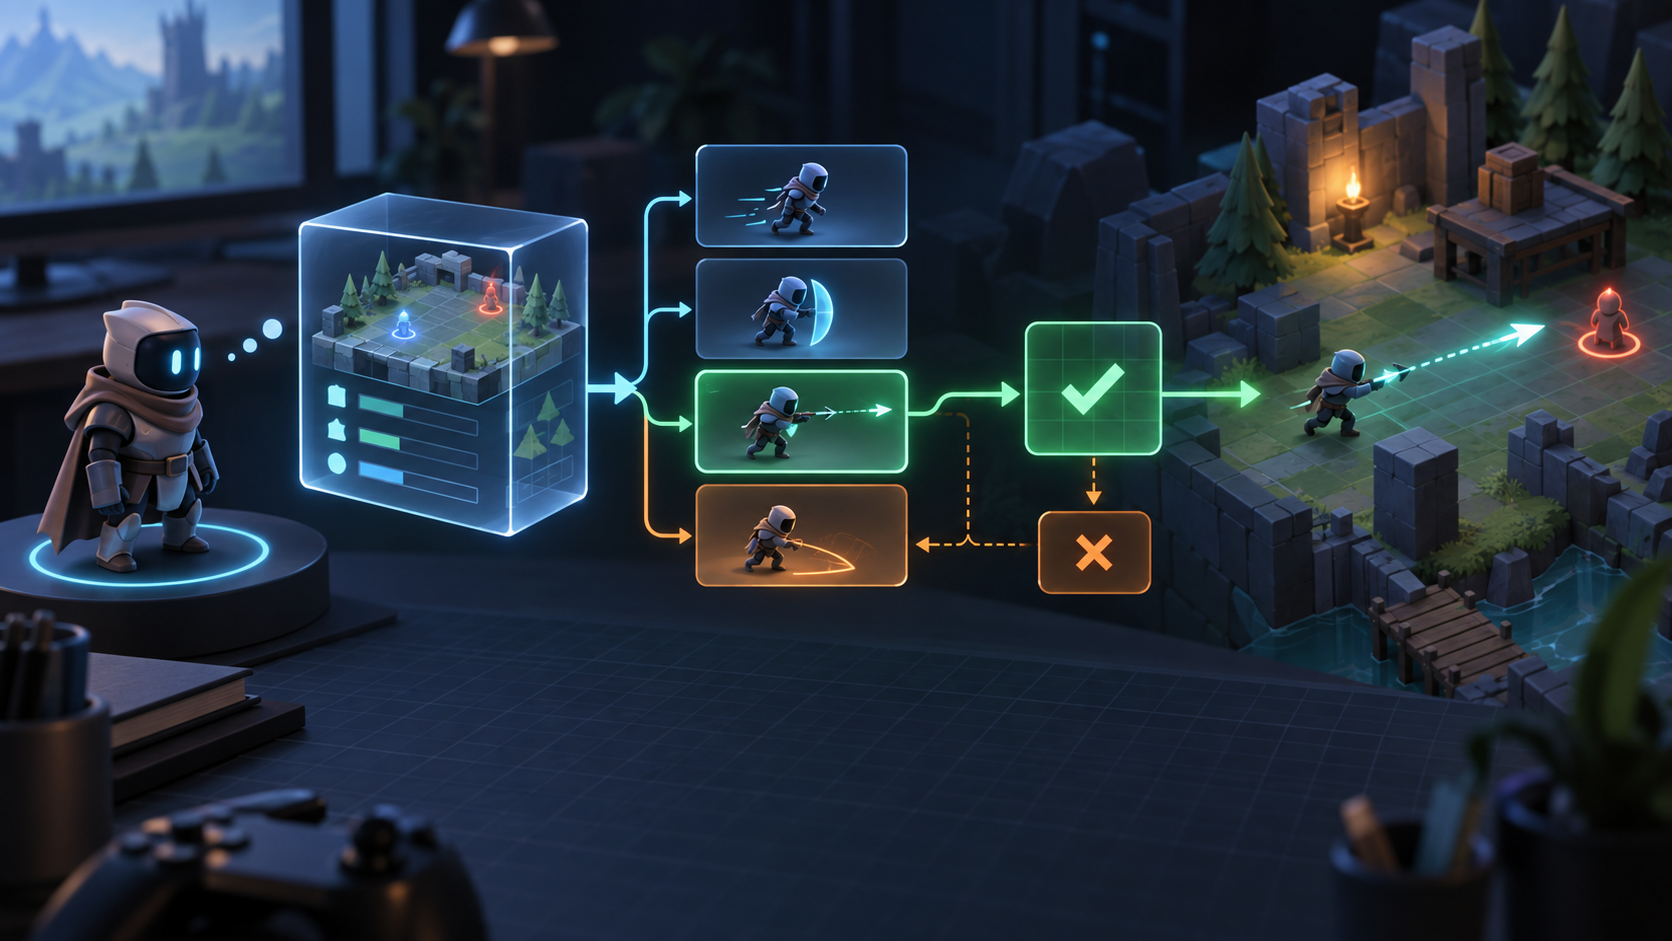
Public JEV materials describe typed primitives such as Choice, Score, and Noul. A Choice selects one item from a defined set. A Score ranks candidates. A Noul answers a bounded yes-or-no question. The game defines the question and allowable result instead of asking for unrestricted prose.
What LLMs are good at
LLMs can write NPC dialogue, summarize quest history, generate mission briefs, explain a design choice, transform natural language into a draft quest, or propose a long-horizon plan. Any plan must still be converted into approved commands and pass the game's validation boundary.
Why not use an LLM for every tick?
Per-tick control makes a general language interface responsible for the most deadline-sensitive part of the game loop. Output may be too slow, verbose, or open-ended, and behavior becomes harder to reproduce. Low-level steering, collision, animation, and safety checks are normally deterministic. Trigger a tactical decision when a threat appears, an action completes, or an objective changes.
A hybrid JEV and LLM architecture
- The LLM handles dialogue, quest interpretation, or a high-level plan.
- Game code translates that result into compact state and closed legal actions.
- JEV chooses, scores, or gates the tactical decision.
- A behavior tree, ability system, or executor performs the action.
- Telemetry records state, latency, validity, and outcome.
Decision checklist
- Known choice, score, or yes-or-no question: JEV may fit.
- Dialogue, prose, code, or open-ended plan: an LLM may fit.
- Can the game validate the result before execution?
- Is there a deadline, fallback, and replayable state?
Compare by layer, not by hype
The most useful comparison asks which layer of the game each system owns. Perception and authoritative state belong to the engine. Tactical selection can use a bounded decision model. Dialogue and narrative can use an LLM. Navigation, animation, physics, and replication should remain deterministic. This layered view avoids the false choice of putting one model in charge of the whole NPC.
Three hybrid patterns
- LLM to JEV: the LLM interprets a player request or quest goal, then game code converts it into a bounded tactical question for JEV.
- JEV to LLM: JEV selects a situation or objective that deserves explanation, while the LLM writes dialogue or a mission update.
- Parallel specialists: JEV makes a time-sensitive choice while an LLM prepares non-blocking dialogue, memory, or content for a later moment.
In all three patterns, the game owns the handoff contract. A natural-language plan is not an executable command, and a typed choice is not permission to bypass validation.
Failure modes to design for
- Open-ended output: convert it into a closed command set before execution.
- Stale state: attach a version and reject results that no longer describe the world.
- Slow response: preserve the current intent or switch to a local policy.
- Prompt drift: keep question schemas versioned and replayable.
- Role confusion: document whether a component chooses, explains, or executes.
Selection matrix
Choose JEV when the candidates are known, the decision must be typed, and the game can evaluate validity. Choose an LLM when language or open-ended generation is the product of the call. Choose neither for a deterministic rule that is already easy to express in code. The best AI architecture often reduces the model's responsibility until its output can be tested like any other subsystem.
For implementation, continue to JEV API usage. For NPC architecture, read JEV NPC. For broader context, see JEV Game AI.