_
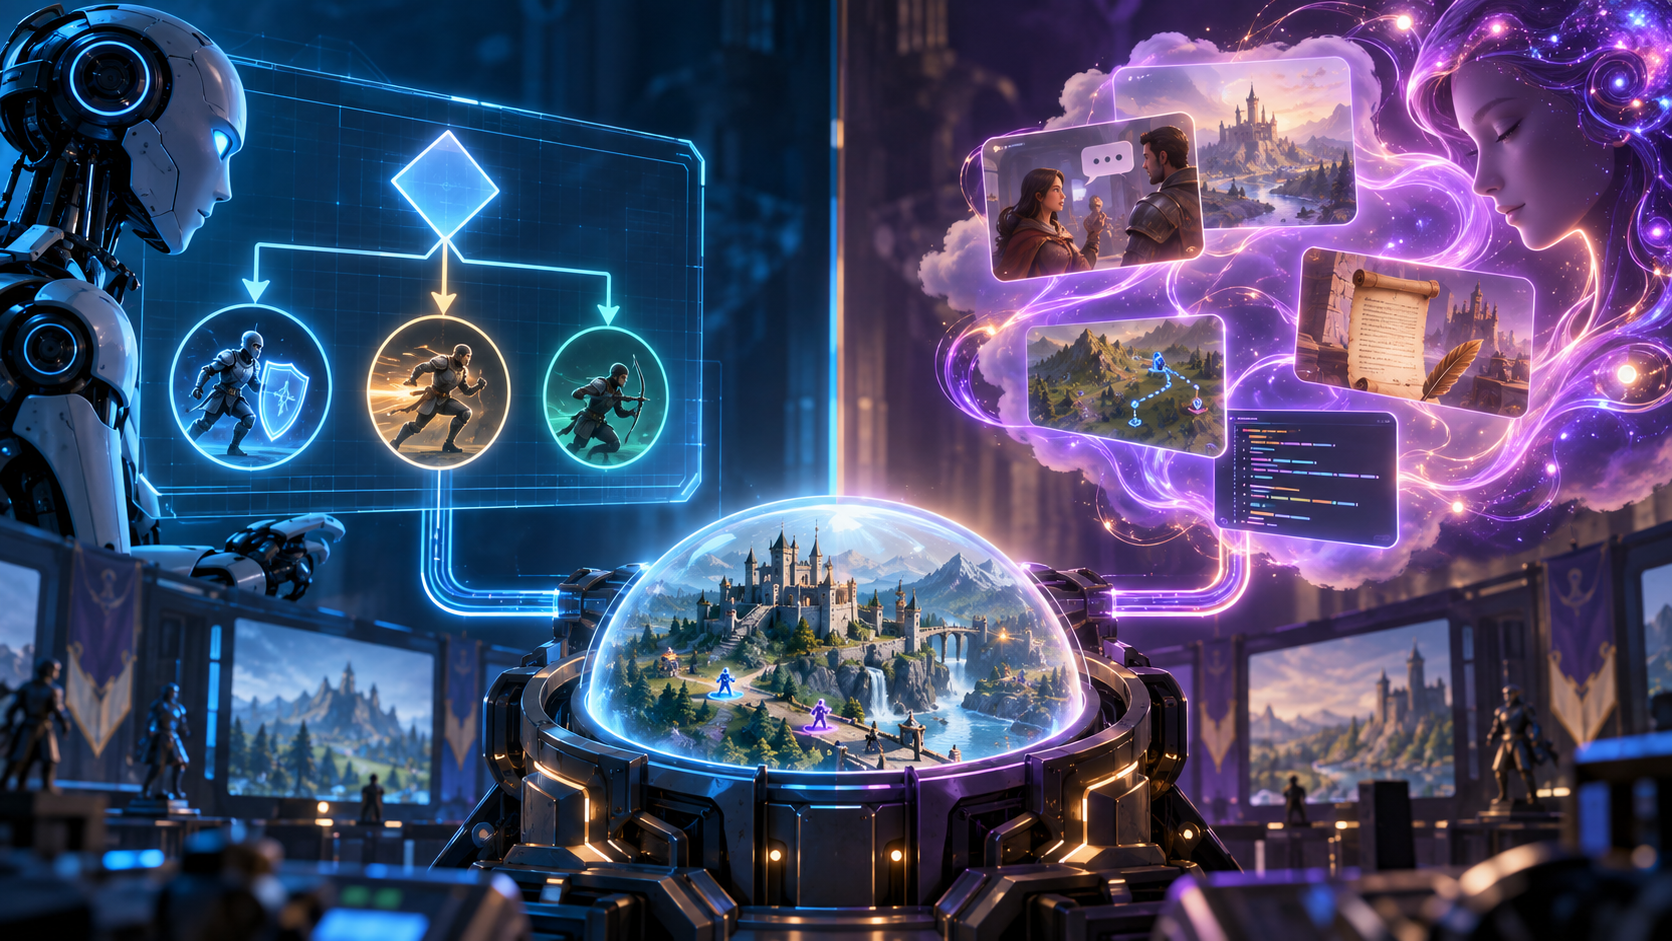
JEV 和 LLM 解决游戏中的不同问题。 LLM 是语言、计划、代码、对话和开放式指令的通用生成器和解释器。 JEV 是一种有界决策能力:它根据键入的问题评估游戏状态投影,并返回受约束的结果,例如 Choice、Score 或是或否判断。最好的架构通常同时使用两者.
简短回答
| 当游戏知道合法选项并需要对其进行键入判断时,请使用 JEV。使用 LLM 进行对话、叙述、解释、代码、开放式生成或长期规划。两者都不应该拥有权威的游戏规则;引擎验证并执行结果. | _能力 JEV 1_输出键入Choice、Score 或有界判断文本、代码、计划、对话或结构化输出最佳适合状态评估和候选行动选择对话、叙述、计划和生成行动空间封闭和验证的候选人开放式可能性游戏角色决策或战术层对话、内容和高层规划_ | JEV 返回什么 |
|---|---|---|
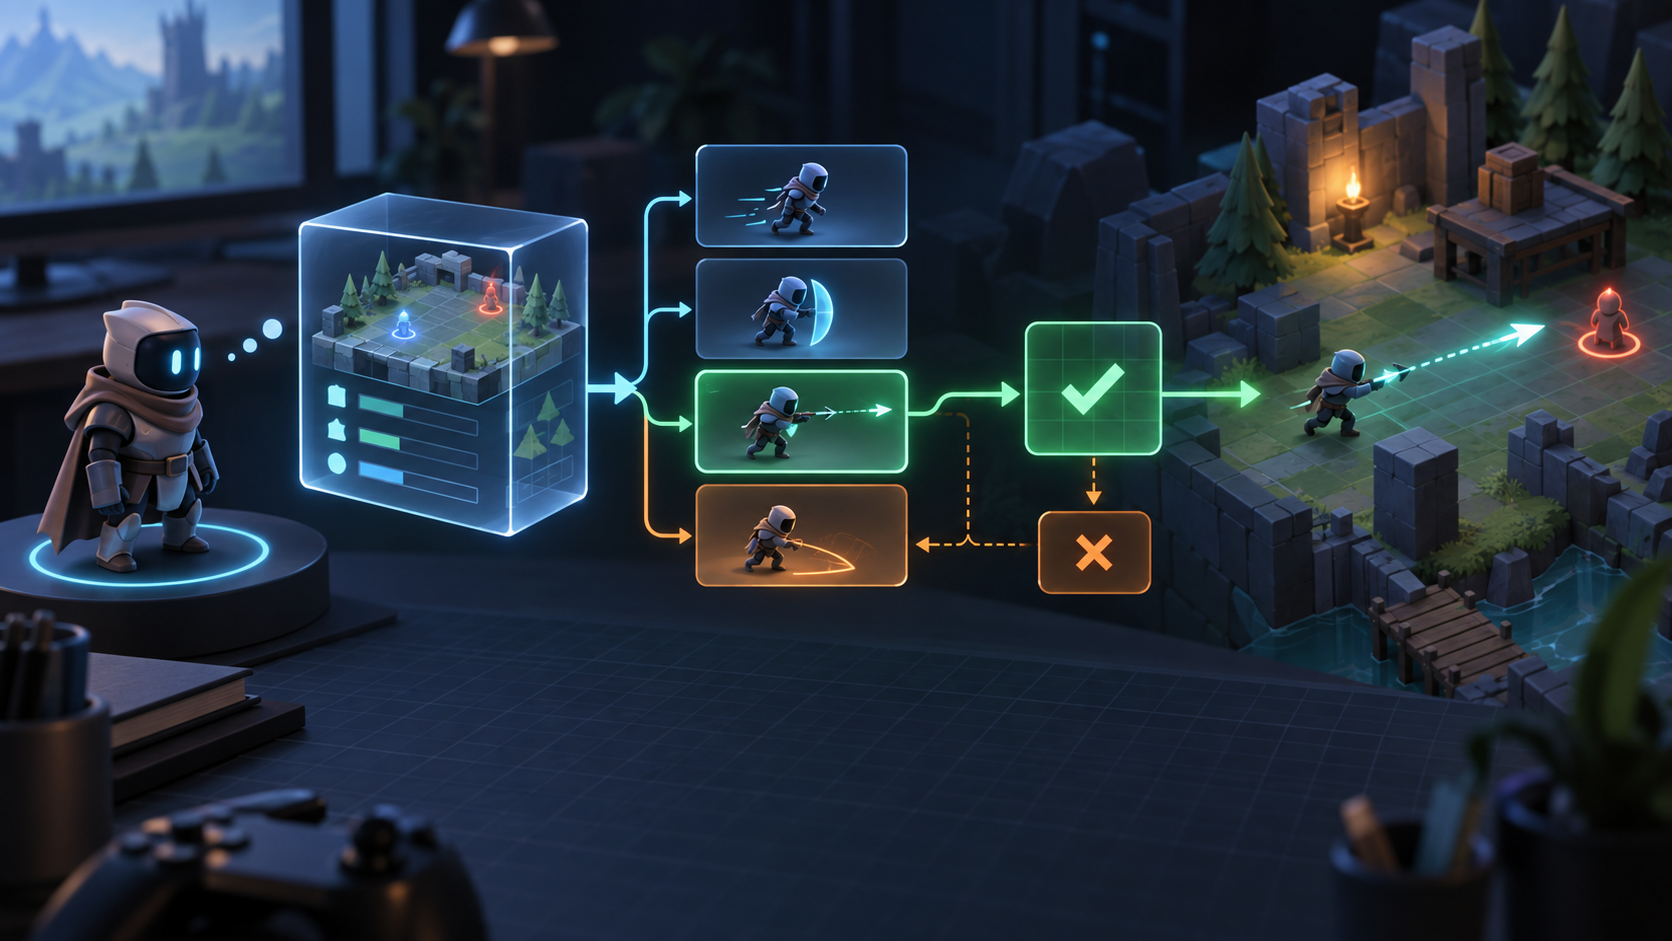
| 公共 JEV 材料描述类型化原语,例如 , ,和。 Choice 从定义的集合中选择一项。 Score 对候选人进行排名。 Noul 回答有界的是或否问题。游戏定义了问题和允许的结果,而不是要求不受限制的散文。 | LLM 擅长什么 | LLMs 可以编写 NPC 对话、总结任务历史、生成任务简介、解释设计 Choice、将自然语言转换为任务草案,或提出长期计划。任何计划仍必须转换为批准的命令并通过游戏的验证边界。 |
| 为什么不为每个刻度使用 LLM ? | Per-tick 控制使通用语言接口负责游戏循环中对最后期限最敏感的部分。输出可能太慢、太冗长或开放式,并且行为变得更难以重现。低级转向、碰撞、动画和安全检查通常是确定性的。当威胁出现、行动完成或目标发生变化时触发战术决策。 | 混合 JEV 和 LLM 架构 |
| _LLM 处理对话、任务解释或高级计划。游戏代码将结果转换为紧凑状态并关闭 可执行动作.JEV 选择 Scores,或关闭战术决策.行为树、能力系统或执行器执行操作.遥测记录状态、延迟、有效性和结果._ | 决策清单 | _已知 Choice、Score 或是或否问题:JEV 可能适合.对话、散文、代码或开放式计划:LLM可能适合。游戏可以验证吗执行前的结果?_是否有截止日期、兜底策略和可重播状态?_ |
| 按层比较,而不是炒作 | 最有用的比较询问每个系统拥有游戏的哪一层。感知和权威状态属于引擎。战术选择可以使用有界决策模型。对话和叙述可以使用 LLM。导航、动画、物理和复制应该保持确定性。这种分层视图避免了错误的 Choice 将一个模型负责整个 NPC. | 三种混合模式 |
_LLM 至 JEV:
LLM 解释玩家请求或任务目标,然后游戏代码将其转换为有界战术问题JEV.JEV 至LLM:_ JEV 选择值得解释的情况或目标,而 LLM 编写对话或任务更新.并行专家: JEV 使时间敏感Choice 而 LLM 则为稍后准备非阻塞对话、记忆或内容。_在所有三种模式中,游戏都拥有移交合同。自然语言计划不是可执行命令,并且键入的 Choice 不允许绕过验证。设计的故障模式_开放式输出:之前将其转换为封闭命令集执行.过时状态:_ 附加版本并拒绝不再描述该结果的结果world.响应缓慢: 保留当前意图或切换到本地政策.提示漂移:
保持问题模式版本化并可重播.角色混淆:
记录组件是否选择、解释或执行._
选择矩阵
当候选人已知时,选择JEV,必须输入决策,并且游戏可以评估有效性。当语言或开放式生成是调用的产物时,选择 LLM。对于已经很容易用代码表达的确定性规则,不要选择任何一个。最好的 AI 架构通常会减少模型的责任,直到可以像任何其他子系统一样测试其输出。
要实施,请继续JEV API用法
- 。对于 NPC 架构,请阅读
- JEV 。有关更广泛的背景信息,请参阅 JEV 游戏 AI
- .
- A behavior tree, ability system, or executor performs the action.
- Telemetry records state, latency, validity, and outcome.
Decision checklist
- Known choice, score, or yes-or-no question: JEV may fit.
- Dialogue, prose, code, or open-ended plan: an LLM may fit.
- Can the game validate the result before execution?
- Is there a deadline, 兜底策略, and replayable state?
Compare by layer, not by hype
The most useful comparison asks which layer of the game each system owns. Perception and authoritative state belong to the engine. Tactical selection can use a bounded decision model. Dialogue and narrative can use an LLM. Navigation, animation, physics, and replication should remain deterministic. This layered view avoids the false choice of putting one model in charge of the whole NPC.
Three hybrid patterns
- LLM to JEV: the LLM interprets a player request or quest goal, then game code converts it into a bounded tactical question for JEV.
- JEV to LLM: JEV selects a situation or objective that deserves explanation, while the LLM writes dialogue or a mission update.
- Parallel specialists: JEV makes a time-sensitive choice while an LLM prepares non-blocking dialogue, memory, or content for a later moment.
In all three patterns, the game owns the handoff contract. A natural-language plan is not an executable command, and a typed choice is not permission to bypass validation.
Failure modes to design for
- Open-ended output: convert it into a closed command set before execution.
- Stale state: attach a version and reject results that no longer describe the world.
- Slow response: preserve the current intent or switch to a local policy.
- Prompt drift: keep question schemas versioned and replayable.
- Role confusion: document whether a component chooses, explains, or executes.
Selection matrix
Choose JEV when the candidates are known, the decision must be typed, and the game can evaluate validity. Choose an LLM when language or open-ended generation is the product of the call. Choose neither for a deterministic rule that is already easy to express in code. The best AI architecture often reduces the model's responsibility until its output can be tested like any other subsystem.
For implementation, continue to JEV API usage. For NPC architecture, read JEV NPC. For broader context, see JEV Game AI.